In February we wrote about agentic engineering and about why less is often more in vibe coding. Nine months later, much of it is no longer true. So here is how we work today.
The short version: AI agents now write code faster than a person can read it. Our real job is therefore to build an environment in which we can trust their results without reading every line ourselves.
TL;DR
- AI is not a trend. Anyone in software development who doesn’t use it actively will run into trouble.
- The big construction sites of early 2026, context engineering, Ralph loops and elaborate prompting, are largely solved.
- The bottleneck today is trust. Whatever an agent delivers has to be checkable automatically.
- Our order: deterministic rules in code first, then agents testing their own work, written instructions last.
- Every change is reviewed by an agent that didn’t write it. For important changes, by three models from three providers.
- Quality remains the top priority. The speed comes from the quality, not the other way round.
AI is no longer a trend
Whether AI “is here to stay” is no longer a question. For a sober overview we recommend two conversations (in German) between Daniel Jung and Prof. Dr. Christian Bauckhage of Fraunhofer IAIS: “KI - Wir haben noch gar nichts gesehen!” and “KI: Schon wieder Dekaden vergangen”. No hype, no doom, a lot of context.
For companies this means the question is no longer whether to use AI, but how well. In software development we see the difference every day.
What has been solved since early 2026
An AI model can only write text on its own. To read files, start programs and run tests, it needs a program around it, the so-called harness. Model plus harness makes an agent. We explain exactly what that is in What is a harness?.
At the start of the year a lot revolved around three problems. The harness has since taken over two of them, the models themselves the third.
The first was context engineering. The context is the model’s working memory, everything it has in view at once during a session. When it got too full, the model lost the thread, and you had to control carefully what went in. Today the harness notices when space runs short. It has the model summarize the history so far and replaces the old history with that summary. This is called compaction. So the harness decides when to summarize, and the model writes the summary. Because models are now trained for exactly this, they keep working afterwards without a noticeable break.
The second was Ralph loops, named after Ralph Wiggum from The Simpsons. A script restarted the same agent over and over until a long task was done. Today an agent works on one task for hours or days. It hands subtasks to sub-agents: further agents with their own fresh context that only report back their result.
The third was prompting. You used to have to write down exactly what you wanted: every step, the format, examples, and ideally what the model must never do. Today it is usually enough to describe the goal the way you would to an experienced colleague. The agent works out the path itself by reading the code, trying things and asking when something is genuinely unclear. You still have to be exact, just somewhere else: not about the path, but about the goal. What does “done” mean, what must not change, and how do you tell that it works? This is called exact coding.
Watch the context meter on the right in the animation. It fills up, gets summarized and fills up again, while the task simply carries on.
These topics kept us busy for a long time. They are no longer the bottleneck.
The new bottleneck: trust
When an agent writes more code in one night than a developer does in a week, nobody can read every line any more. So the question is: how do we know the result is right?
The best answer we know comes from Lauren Tan. She is a software engineer at SpaceXSI, where she works on Grok Bot. By her account, her team ships around 11,000 changes to production a month, and only about half a percent of them have to be reverted. In her talk “All Code Is Slop (Except Mine)” at the AI Engineer Code Summit she describes how.
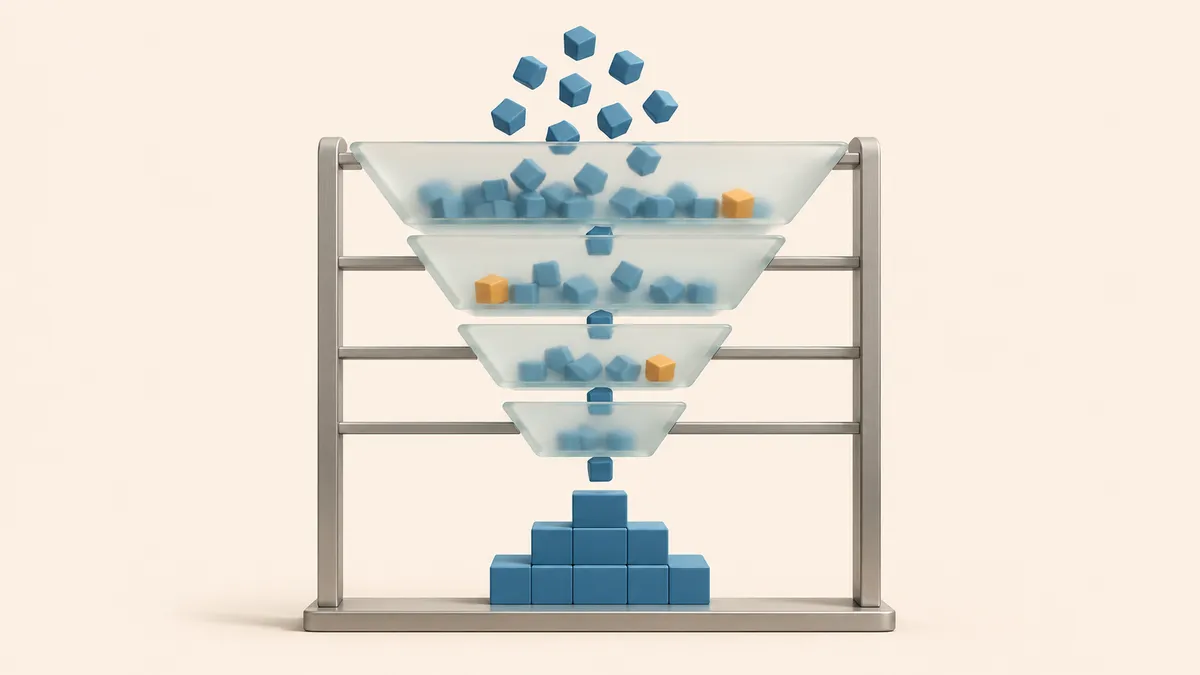
Her core point: you don’t simply trust agents. You invest in their environment until you can trust them. She draws an inverted pyramid for this. At the top, where it is widest, is where most of the work belongs:
- Code and architecture: clear structures, clean boundaries between the parts.
- Deterministic checks: programs that check code automatically, and tests.
- Verification: the agent runs the software itself and proves that it works.
- Prose: written instructions, only for what needs real judgment.
Each layer catches different mistakes. In the animation, every mistake falls until a layer stops it.
We follow this order very closely. The next three sections go through it from top to bottom.
If a rule can check it, a rule checks it
Agents learn mostly from the code they find. A workaround that gets in once is copied by the next agent, because it looks like the usual way. An agent can skim past a written instruction. It cannot skim past a rule that checks the code automatically.
For such rules we use a linter in LIVOI. That is a program that reads code without running it and looks for known patterns of mistakes. Ours is called Ruff. On top of that, ty checks whether the data types fit together.
Here is an example that shows why this is about more than style. LIVOI consists of several services: an API, a worker for background jobs, a scheduler and a few more. Each runs in its own container. Code that all of them need lives in a shared folder that is copied into every container.
On a developer’s machine, though, everything sits in one repository. If an agent imports something from the API inside the worker, it works perfectly there, and the tests pass. Only in production does it turn out that this code doesn’t exist in the worker’s container at all. No review reliably catches this kind of mistake, because the code looks completely normal.
So a rule now forbids these imports. This is how it reads in the worker’s configuration:
[lint.flake8-tidy-imports.banned-api]
"backend".msg = "Use shared code or a service contract instead of importing the API."
And this is what happens when an agent tries anyway:
$ ruff check celery_worker/
celery_worker/tasks/reminders.py:3:1: TID251 `backend` is banned: Use shared code or a service contract instead of importing the API.
The message doesn’t just say what is wrong, it also says what the agent should do instead. That makes it an instruction that cannot be skimmed past. Every service has its own list, and the shared code may not import any of the services.
Tan describes almost the same case in her talk: in her desktop app, two parts of the program may not import each other, and a lint rule enforces it. She names further levers you can pull with deterministic rules:
- Ban tricky tools outright. Some functions can only be used well with a lot of nuance, and that is exactly what agents lack. Her team only allows such a function in a few central places. The mistake doesn’t become rarer, it becomes impossible.
- Ban most code comments. Comments in code go stale, and agents like to use them to justify why they built a workaround. The next agent reads the justification and copies the workaround.
- Write error messages that lead to the root cause. A good message tells the agent what to change at the root, not how to get around the check.
- Stop new cases first, then clean up. A new rule first stops every further occurrence. You clean up the old places afterwards, at your own pace.
In the same spirit as the ban on code comments, we close escape hatches. An agent at our company may not switch off a check wholesale. Anyone who wants to suppress a finding has to name exactly which one. That keeps every exception visible, so a review can ask about it directly.
Our rule of thumb: every correction we make for the second time becomes a rule.
Translated for decision-makers: a rule is a quality check you set up once, and it then runs on every single change at no extra cost.
Verification is everything
An agent that cannot try out its own work is guessing. That is why every agent at our company can start its own disposable copy of LIVOI, with exactly the state it is working on. It signs in to the browser with a test account, clicks through the changed feature, checks the API’s responses and tears everything down afterwards.
This creates a loop: change, start, look, correct. Until the result is proven. “The tests are green” is not enough. It is proven when the feature does what it should.
The animation shows why that makes a difference. The linter and the tests are happy. Only when the agent opens the page in the browser does it see that a deadline is shown one day early.
At the end the agent hands over evidence: test results, API responses, screenshots. Our review thus shifts from reading every line to checking this evidence. Tan reports that most of her AI budget now goes into verification. We see it the same way, because this is where trust comes from.
Instructions come last
Text only comes at the bottom of the pyramid. Over the past weeks we have written a set of so-called skills for LIVOI. A skill is a short work instruction that an agent loads only when a task needs it. That keeps its working memory free for what matters.
One instruction, for example, first clarifies whether a request is just a question, asks for a plan, or really wants something built. Another defines which evidence actually proves a change. A third checks code for real bugs rather than matters of taste, a fourth simplifies an implementation without changing its behavior. Sensitive areas such as database changes, migrations, performance and tests have their own.
When instructions contradict each other, a fixed order applies: what the person says comes first. Then the specific task, then the project’s rules, and only then the method of an instruction.
Here too we change something almost daily. The goal is for our speed to keep rising without quality suffering.
Reviews with fresh eyes
Whoever wrote a text is the worst at finding their own typos. They read what they meant to write, not what is there. Agents are the same: the agent that built a change knows its assumptions and overlooks exactly those.
That is why every change is reviewed by a separate review agent with fresh context. It gets the code and the goal, but not the path that led there.
For important changes we go further. Three strong models from three different providers review independently and give a score from 1 to 10. We fix the findings and have them review again until all three are satisfied. Different models have different blind spots, so together they find more than any single one.
For smaller changes, a single reviewing model over a few rounds is enough. Every finding is classified: blocks the release, real bug, or nitpick. We fix with the smallest possible change. And we push back when a suggestion only inflates the scope, because reviewing models also like to suggest more than necessary.
Nothing reaches production without a person’s approval.
Reviews with fresh context are the next big topic for us. This is where we are changing the most right now.
What this means for managing directors and decision-makers
- The edge lies in the environment, not the model. Anyone can buy the best models. Rules, tests and verification belong to you and stay when the model changes.
- Automation amplifies what is already there. If agents produce messy code today, more automation only produces more of it.
- Speed and quality are not a contradiction, as soon as quality is checked automatically.
- The developer’s role is changing. Less typing, more building guardrails, owning architecture and checking evidence. You can compare it to gardening: you no longer plant every plant yourself, you build the beds, trellises and fences that make new growth go in the right direction.
- Start small. Every correction you make for the second time is a candidate for a rule.
Limits
- No rule replaces product decisions. People decide what gets built.
- Verification mainly costs time. An agent that starts the software and clicks through it takes longer than one that only writes code. It costs real money where checks run on build servers billed by the minute. Both are cheaper than a bug in production.
- Without a solid codebase none of this helps much. With grown legacy systems, the first step is often cleaning up.
- None of this is a final state. What works today we replace tomorrow when we find something better.
Frequently asked questions
Do we need a large development team for this?
No. Small teams in particular benefit, because rules and verification take over work that used to need additional reviewers.
Does a person still read the code?
Yes, where it matters: architecture, security, sensitive data changes. Routine details are checked by rules, tests and review agents. A person always gives the final approval.
Which model is the best?
That changes every few weeks. That’s why we don’t tie ourselves to one provider and have important changes reviewed by several models.
What does your technical setup look like?
Deliberately simple, and it changes all the time. If you have questions about it, get in touch. We are happy to talk.
If you try only one thing tomorrow: notice which correction you are making for the second time, and ask whether a program could have found it. If you want to introduce agentic engineering in your team with rules, verification and clear roles, talk to us.